Op-ed
91% of public data can't be read by AI without document structuring
Korea Deep LearningPublished
Kim Ji-hyun, CEO of Korea Deep Learning, wrote an op-ed for AI Times titled "91% of public data can't be read by AI without document structuring."
Digitization is done, but AI still can't read
The op-ed points to a gap on the government's path from digital transformation (DX) to "administrative transformation," which brings AI into every stage of administration. Many government agencies say they have finished digitizing their documents, but what they have are electronic documents for people to look at. In PDF, HWP and image files, AI reads only the text without understanding the structure. Tables break, formulas are handled as images, and handwritten entries and signatures never become data. The author sees more than 90% of administrative documents as sitting in a "data blind spot" from AI's point of view.
The reality: 91.1% is unstructured
The evidence cited is "The State of AI Use in the Public Sector," material from the October 2025 National Assembly audit prepared by the office of lawmaker Wi Seong-gon. It shows that 91.1% of the documents held by public institutions exist in unstructured formats that are hard for AI to use. The author reads this not as a lack of technology but as a problem of documents never having been designed, from the start, in a structure AI can interpret.
The op-ed also gives examples. One ministry's business plan contains dozens of tables, graphs, notes and formulas. OCR can pull out the characters, but it cannot interpret which policy items and budget structure a table explains. The same word can also mean different things at different institutions. At one institution, "review" means an advisory opinion; at another, it is a formal step before approval. That is why, the author argues, "structuring by units of meaning" is needed, going beyond text recognition to grasp the structure of a document and the relationships within it.
"For AI to read them, documents have to be translated into 'the language of data.'"
— Kim Ji-hyun, CEO, Korea Deep Learning
The bottleneck is not technology but the language of data
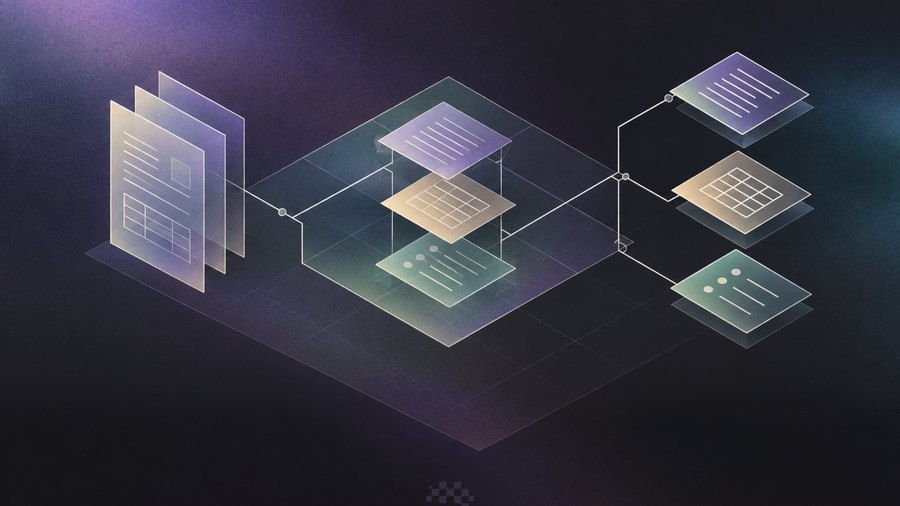
Existing administrative data was written for people to read, but AI can interpret it only when its structure is expressed explicitly. To AI, line breaks, the order of table columns and the position of fields all carry meaning. The solution the author proposes is document structuring: using parsing to analyze layout, relationships between fields, table hierarchies and paragraph flow, and converting them into a form AI can understand. Korea Deep Learning's DEEP Agent+ analyzes text, tables, formulas, figures, notes and layout together to restore document structure, and turns unstructured documents into databases that can be used for search, summarization, classification and statistical analysis.
Administrative efficiency starts with structuring
The conclusion is that bringing in AI does not make administration more efficient on its own. Speed and accuracy depend on how ready the data is, and converting documents into electronic files alone does not turn them into data AI can read. Data, the author argues, must become a source of understanding and judgment rather than something to be stored.
"The bottleneck in administration is not the lack of new systems, but the failure to prepare data in a form AI can understand."
The full op-ed was published in AI Times.
About Korea Deep Learning
Korea Deep Learning (KDL), founded in 2019, is an enterprise AI agent company. Built on KDL Frontier, its own vision-language model (VLM) specialized for documents, KDL makes AI agents that take on and complete the document work of businesses and public institutions. Its main products are DEEP OCR, DEEP Parser, DEEP Agent and DEEP Ops.