Technology and architecture
What Is Document Classification: The First Gate That Splits Merged Files into Work Units, A Complete Guide
Korea Deep LearningPublished
Document classification (Document Classification) is the process of identifying the form type of an incoming file. When several documents arrive bundled together, it splits them into individual documents, assigns a type to each piece, and passes them on to the next stage of processing.
Why document classification is needed
One file is not one document.
When automation is evaluated, most of the discussion starts with recognition accuracy. But when you open an actual intake folder, there is a different problem in front of it. A single file received by fax contains an application form, an ID copy, a bank account copy, and a confirmation letter, all joined together in no particular order. Before reading any values, staff must first open the file and visually work out where the application ends and the bank account copy begins. In one financial institution's measurements, this checking and sorting alone took 2 to 4 minutes per case.
No matter how accurate the recognition model is, automation cannot start without this step. Without knowing what form a page belongs to, it is not decided what to extract. Document classification is not an add-on feature of automation. It is the entry point.
The precise definition of document classification: how it differs from document recognition
Three axes that separate recognition and classification
First, the target differs. Recognition targets the characters and tables within a page. Classification targets the boundaries between pages and the overall impression a page gives. Non-value elements such as logos, form titles, table layout, and printed notices can actually be the basis for judgment.
Second, the goal differs. The goal of recognition is to transcribe what is written accurately. The goal of classification is to decide how many documents this file splits into and what type to assign to each. For the same page, recognition answers what is written on it, while classification answers what kind of document it is.
Third, the performance metrics differ. Recognition is measured by character accuracy or item accuracy. Classification is measured by whether the type judgment was correct. In real validation, there are financial cases where document type classification accuracy was confirmed to be high and public-sector cases where it was confirmed to be lower. This means the value varies greatly depending on how finely the type system is divided and how similar the forms are to one another.
The two processes are not alternatives. If the classification result is wrong, the extraction that follows starts with the wrong item table, so the more accurate the recognition, the more plausible the error looks. Keeping the order is safer.
Five conditions for putting document classification into operation
Five conditions for document classification in real operation
First, it must find document boundaries on its own. In an environment where several documents arrive merged into one PDF, the file must be split into pieces before type judgment can happen. A method that assigns a type to each page alone breaks multi-page documents into separate sheets, so the ability to judge whether consecutive pages belong to the same document is also required.
Second, the type system must be designed around business standards. In one card financial institution's automation, the team organized the initial document groups and set up the classification code system before moving on to extraction. If the code system is too coarse, different forms get grouped under one type and the extraction items go out of line. If it is too fine, judgment becomes harder and accuracy drops.
Third, similar-looking forms must be distinguished. In real work there are many form pairs, such as a new enrollment application and a change-of-information application, that have nearly the same layout and differ only in a few characters of the title. If judgment relies only on the overall impression, errors concentrate on these pairs. The design therefore needs to check decisive clues such as the title and the document number together.
Fourth, it must handle revised forms. Government and financial forms are revised periodically. If a model must be retrained each time a new form arrives, the operating burden keeps growing. Managing type definitions as data and keeping the change history as versions lowers the maintenance cost.
Fifth, cases that cannot be classified must be set aside. If every file is forced into some type, errors quietly flow downstream. Cases with low confidence should be left unclassified and routed to staff review. Only with such a flow is the reliability of the whole automation maintained.
How to apply document classification in practice
Design backward from the intake channel
Classification design starts not with the model but with the intake route. Whether files arrive by electronic fax, are scanned at branch offices, or are uploaded as mobile photos, the condition of the file differs completely.
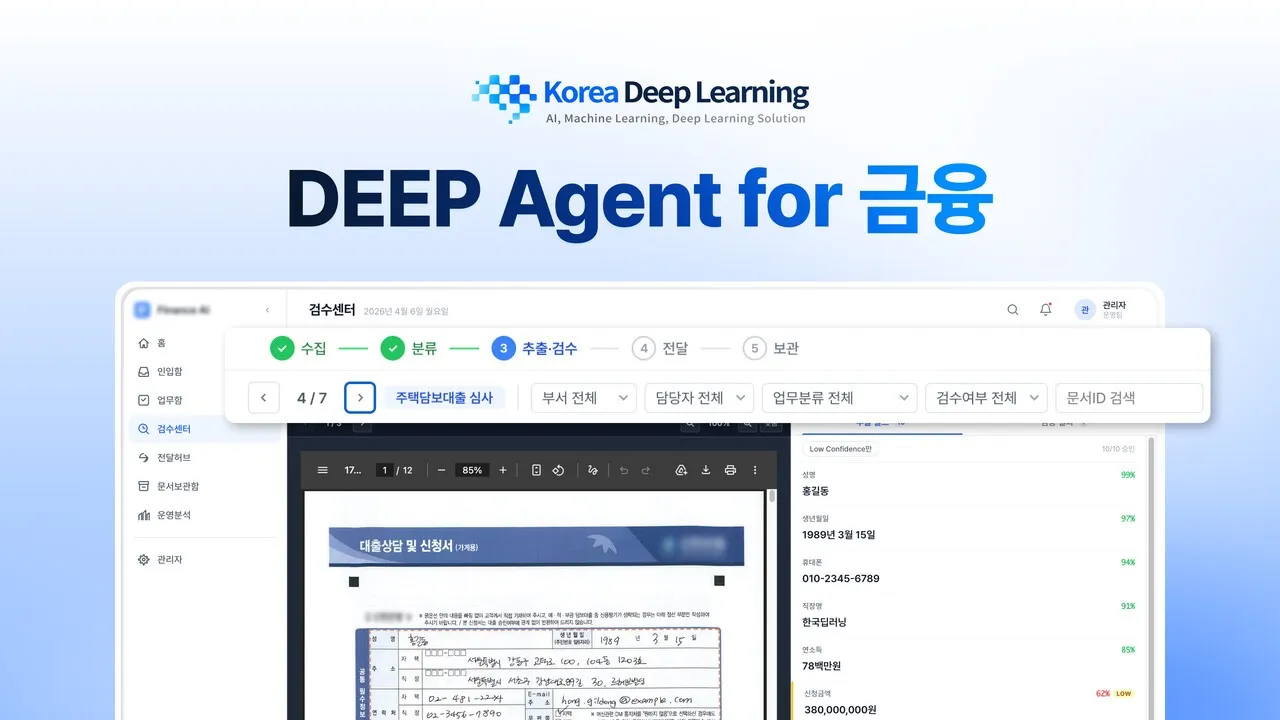
Looking at actual operating flows, the sequence runs: electronic fax intake, splitting merged PDFs, document classification, item extraction, post-processing, verification, loading into the document management system, linking to automation tools, and registration in the core business system. Classification is the third link in this chain, and a case misjudged here carries its error through every stage that follows. For that reason, it is wise to prepare an operating environment where staff can review and correct classification results on a verification screen.
Keep classification and extraction separate
If classification and extraction are combined into a single process, the whole thing must be reworked each time a form is added. Keeping the two stages separate means the classification system only needs its type definitions edited, and extraction only needs its per-type item schema edited to respond.
From a technical standpoint, a model that interprets the visual information and context of the whole document is advantageous. Rule-based methods that read the title in a fixed position fail right away on documents that are skewed or have the top cut off. Real intake documents even include cases where a dark band at the top of a scan, caused by folding, swallowed the form title.
Document classification in the Korean context
In Korean finance and the public sector, faxes still remain on the intake route. Documents that have been retransmitted several times end up with different date formats stacked on the same line, and low resolution blurs the strokes of the form title. Even under these conditions, judging the type requires combining clues from the whole document rather than from a single title area.
Document format is also a condition. Hangul word processor files, scanned PDFs, and image files arrive mixed within one business process, so each format needs different preprocessing. The multi-layer table structures and circled-number item markers specific to government forms act both as clues for type judgment and as obstacles.
Manage the classification code system as a document
The classification system should not be hidden inside the model. It should be managed as a document that staff can read and edit. When the number of types grows to hundreds, knowing which code points to which form becomes business knowledge in itself.
The management document should record, for each code, the form name, the issuing agency, a representative sample file, and the list of items to extract from that type. If there are similar forms, it should also state what distinguishes them. For example, the criterion that tells a new enrollment application from a change-of-information application by two characters in the form title should be written down here.
With this document in place, the system survives changes in staff, and when a new form arrives it provides a basis for deciding whether to add it to an existing type or create a new one.
Feed review results back into classification standards
Classification is not a process you build once and forget. Once in operation, unexpected forms keep arriving, and staff end up correcting judgments.
Gathering these correction records becomes the basis for improvement. If corrections repeat for a certain type, it is a signal that the definition of that type is ambiguous or that its boundary overlaps with a similar form. If the share of cases falling into unclassified rises, it means new forms are coming in.
Reviewing the correction records regularly, adjusting the type definitions, and keeping those changes as versions prevents accuracy from declining over time.
Calculate throughput and parallel configuration together
Classification sits at the front of the whole flow, so if it backs up, everything after it backs up too. This is why you need to look not only at the monthly average volume but also at how concentrated the arrivals are during peak hours.
In one operating case, a screening business with about 15,000 cases per month received an average of six document types per case and an average of fifteen pages per case. The count is 15,000 cases, but the page count exceeds 200,000 pages. For classification, it is more accurate to size processing capacity by pages rather than by case count.
Also consider a setup that sends urgent cases through first. In work where timing determines the outcome, such as receiving victim relief applications, it is better to have a separate priority processing path.
Frequently asked questions
Can it process several documents that arrive in one PDF?
Yes. Before the type is judged, a step runs that finds the document boundaries and splits the file into pieces. Without this function, the extraction that follows proceeds with the wrong item table.
How accurate is the classification?
It depends on the document group. Some cases validated on financial documents showed high accuracy, while validation on public documents showed lower accuracy. It is more accurate to use the value measured on your own documents as the baseline.
What happens when a new form is added?
The response is to add a type definition. Rather than retraining the model parameters, you revise the classification system and item schema and keep the changes as versions, which lowers the operating burden.
Are similar-looking forms distinguished?
Yes. However, errors concentrate on form pairs with nearly identical layouts, so the design needs to include decisive clues, such as the form title and document number, in the judgment basis.
What happens to documents that cannot be classified?
They are separated as unclassified and become subject to staff review. Not forcing low-confidence cases into a type is the way to reduce overall errors.
How many types can one file contain?
There is no limit. In actual operation, cases have been confirmed where one case brought in an average of six types and fifteen pages. Similarity between forms matters more for difficulty than the number of types.
How are the corrections staff make to classification results used?
They are gathered and used as grounds for revising type definitions. If corrections repeat for a certain type, it is treated as a sign that the definition is ambiguous or that its boundary overlaps with another form.
Can faxed low-resolution documents be classified?
Yes. Because judgment combines clues from the whole document rather than depending on a single spot such as the form title, it can respond even when the top part is damaged.
Send us one merged intake file, and we will return the splitting and classification results as they are.
Contact us