Data and quality
What Is AI-Ready Data: A Complete Guide to Data Organized So AI Can Read and Use It Right Away
KDLPublished
AI-ready data is documents and records organized with structure, sources, quality and usage conditions so that AI can search, judge and process them right away. It is the starting point for using generative AI and AI Agents in work.
Why AI-Ready Data Is Needed
Having files did not mean you could use them.
Many organizations have already digitized their documents. Paper forms became scanned files, and reports and regulations pile up as word processor files and PDFs. Yet when generative AI is connected to them, the answers you want often do not come out. Tables are flattened into blocks of text, there is no way to tell which page of which document an answer came from, and superseded regulations get mixed in with current ones in search.
The problem often lies more in the data than in the AI model. There is a gap between a file a person can open and read, and data that AI can accurately find and use. If you change only the model without closing that gap, the results will not change much.
When AI Agents move to processing work based on documents, the requirements rise further. They must be able to show the location in the source text that a judgment was based on, and sensitive information must not be exposed to people without access rights.
A Precise Definition of AI-Ready Data: How It Differs from Digitized Data
Three Axes That Separate Digitized Data and AI-Ready Data
First, the structure differs. Digitized data is paper turned into files, so the distinction between titles, body text, tables and footnotes often no longer exists. AI-ready data keeps title hierarchy, table rows and columns, and image descriptions, so the machine can recognize the structure.
Second, the context differs. Digitized data usually keeps little more than the file name. AI-ready data attaches metadata such as document type, date written, period of validity, the original file and page number to each piece of content, which narrows the search scope and makes it possible to trace back to the source.
Third, the management state differs. Digitized data is often stored without any quality check. AI-ready data has been checked to confirm the conversion was done correctly, personal information has been masked, and who may view it has been defined.
Digitization is the first step toward AI-ready data. If scanning and digitization are done, there remains a stage of structuring and verifying the result.
The Five Conditions of AI-Ready Data
Five Conditions for Data That AI Can Use Right Away
First, the structure is preserved. Tables stay as tables and lists stay as lists, so the relationships between cell values are not broken.
Second, metadata is attached. Information that serves as the basis for filtering search, such as document type, date and department, is needed.
Third, it is linked to its sources. Each piece of content keeps its original file, page and location, so a person can verify the AI's answer.
Fourth, quality is confirmed. There must be a record that recognition errors and omissions were checked on a sample.
Fifth, permissions and de-identification are reflected. Sensitive information is masked, and viewing permissions are managed together with the data.
Rather than meeting all five at once, set priorities according to the purpose of use. For internal search, structure and metadata come first. For use with an external service, permissions and de-identification must be checked first.
How to Make AI-Ready Data in Practice
Decide the Use First and Narrow the Scope
Trying to organize every document you hold all at once will never finish. Decide first on the work to apply it to, such as answering questions about regulations, reviewing contracts or handling civil complaints, and start with the group of documents that work requires.
Once the work is decided, the metadata needed and the quality level required also become clear. If you collect the real list of questions in advance, you can immediately evaluate whether answers come out of the organized data.
Convert While Preserving the Structure from the Original
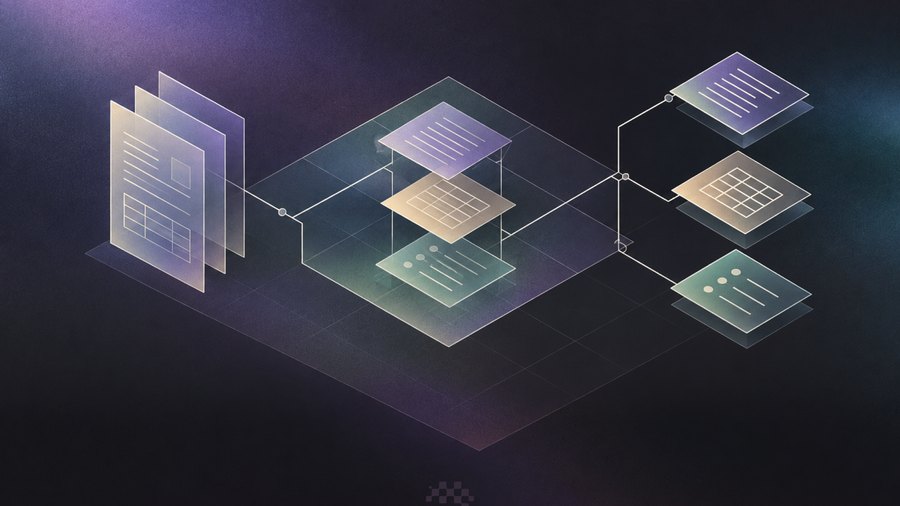
Parse scanned images, PDFs and word processor files, and separate and extract text, tables, images and page information. Save the results in a format that downstream systems can read easily, such as JSON or Markdown, and where the data will be used for search, split it into chunks by meaning.
In a public-sector case of building a generative AI platform, the scope of preprocessing was set as extracting text, tables, images, page information, chunks and keywords, then applying de-identification, so that the output became structured data ready to be loaded into a database.
Check Quality and Permissions Before Loading
Compare the conversion results against the originals, and check on a sample whether the table structure has collapsed or any pages are missing. Mask personal information before loading, and link each document's viewing permissions so that they also apply at the search stage. When an original is revised, manage versions so that the data is updated as well.
If a problem is found after loading, you must trace back to the answers and processing results already produced from that data, so checking before loading costs less.
AI-Ready Data in the Domestic Environment
Many domestic public agencies and companies hold documents in Hangul word processor files, so whether the file can be read with its structure intact is the first hurdle. Approval boxes, seals and complexly merged tables are common, and overseas tools tend to break their structure easily.
In finance and the public sector, original documents are hard to send outside, so conversion and de-identification must be possible inside the internal environment. In a network-separated environment, first consider a setup where the conversion tools and the storage sit inside the same internal network.
Frequently asked questions
Do I need to redo work on documents that are already digitized?
You do not need to recreate the files. What is added is parsing the existing files and attaching structure and metadata to them.
Are AI-ready data and RAG preprocessing the same thing?
RAG preprocessing is the preparation work for search-based generative AI. AI-ready data refers to a data state that can be used not only for search but also for extraction and automation.
Is extracting only the text enough?
If tables and document structure disappear, AI can easily misread the relationship between figures and items. For regulations and reports, which contain many tables, preserving structure matters more.
How good does the quality need to be?
It depends on the work. For work that cites amounts or clauses, set a high bar for sample checks. For reference search, you can first favor broader coverage.
What if the documents contain personal information?
De-identify them before loading, and separate the originals so that only people with permission can view them. Also confirm that permissions apply to the search results.
Once built, can it be used indefinitely?
Documents are revised and new ones are created continuously. Build a pipeline so that new documents are converted by the same procedure, so the data does not go stale.
Where is the best place to start?
Starting with the group of documents that receives the most questions or takes the longest to search makes the effect easier to confirm.
Tell us the types and formats of the documents you want to connect to AI, and we will outline the scope of conversion and the checkpoints needed to make them AI-ready data.
Contact us